Intro
So, I’ve been working on TaskGraph, an asynchronous batch scheduling task library and related tools to create bindings from C to C# and potentially other languages.
With the core API mainly done, I needed a sufficient demo where I can demo the performance of scheduling tasks and what better demo than a CPU ray tracer in C#?
Why C# if TaskGraph is written in C99?
I chose C# because interop provides a slight performance hit as the .NET context has to be paused when I exit and execute native functions. Since TaskGraph requires a function pointer to execute, the .NET context is resumed when executing scheduled tasks.
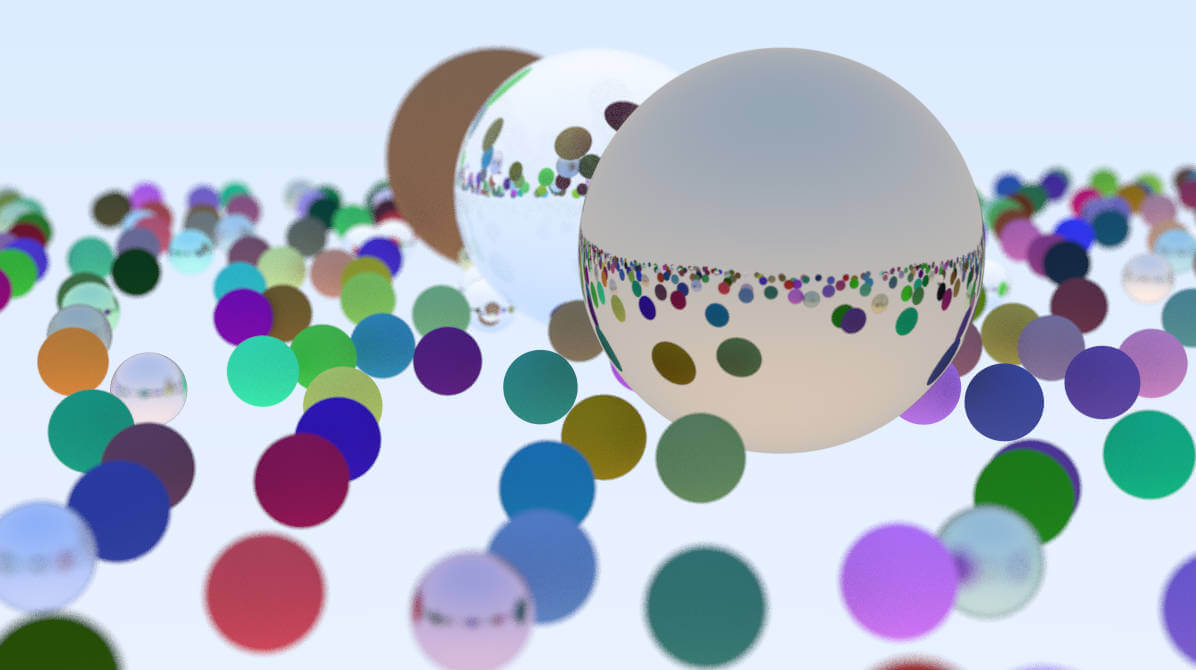
Above is the final image rendered that is ray traced, it contains lambert, metallic, glass materials, and depth of field.
The CPU Ray Tracer
So the CPU ray tracer is the same one outlined in the book, Ray Tracing in One Weekend. The book uses objects to represent materials and hit objects, but if I want to write a highly performant ray tracer, I opted to stick with blittable structs that can be laid out in memory sequentially. The problem with managed objects in C# is that objects are allocated randomly in the heap. .NET’s garbage collector will free unused resources and move objects so that the memory is effectively defragmented, but any array of objects is effectively an array of pointers, meaning I cannot guarantee sequential memory addresses when accessing each element in an array.
I won’t go over the contents of Ray Tracing in One Weekend, as the book thoroughly goes over how to build a ray tracer, but I will go over the different stages of performance.
Scalar Ray Tracer
Some background
In any kind of physically based rendering, we represent materials by certain properties. This ray tracer uses the following material properties outlined in the table below.
| Surface Type | Properties |
|---|---|
| Lambert | Albedo (Vector3) |
| Metallic | Albedo (Vector3), Fuzz (float) |
| Glass | RefractionIndex (float) |
The first iteration
Each material type was represented by a union struct in C# and stored in an array. So I do not use a typical
union as outlined in the MSDN documentation
here.
What I do instead is create a struct with explicit field offsets like so:
[StructLayout(LayoutKind.Explicit)]
public struct Material : IMaterial, IEquatable<Material> {
    [FieldOffset(0)]
    public MaterialType MaterialType;
    [FieldOffset(4)]
    public float RefractionIndex;
    [FieldOffset(4)]
    public Vector3 Albedo;
    [FieldOffset(16)]
    public float Fuzz;
}
If I were to draw the struct visually, it would look like so:
Material

┌──────────────┬───────────────────────────────────────┬──────────────┐
│ MaterialType │              Overlapping              │     Fuzz     │
│    0..3      │                 4..15                 │    16..19    │
├──────────────┼───────────────────────────────────────┼──────────────┤
│   4 bytes    │                                       │   4 bytes    │
│              │  RefractionIndex:  4..7               │              │
│              │  Albedo:           4..15              │              │
└──────────────┴───────────────────────────────────────┴──────────────┘
0              4                                      16             20
│              │                                       │              │
└──────────────┴───────────────────────────────────────┴──────────────┘
So this struct stores properties for lambert, metallic, and glass surface types all in 20 bytes. If I chose to create a struct per material type, then a lambert material would be 12 bytes, a metallic material would be 20 bytes, and a glass material would be 4 bytes.
The size would vary per struct, but I would need to store them in 3 separate arrays. For the simplicity of my
demo, I chose to use a union such that all materials are effectively 20 bytes with an enum defining the
type of material. For 500 materials, that is 10000 bytes or about 9.77 kb of material data.
Each sphere embedded the material and the whole CPU Ray tracer took about 97121 ms on 8 threads for a 1200x675 px image with 50 bounces per ray and 100 samples per pixel. That’s about 1.6 minutes to render and write to disk. That’s not bad but honestly, it is pretty slow.
Speeding up the scalar code
The initial implementation of the CPU ray tracer is entirely naive. For each pixel, shoot a bunch of rays, and then check against 500 spheres to see if the ray hits. To improve the scalar code, I introduced a bounding volume hierarchy (BVH tree).
None of the spheres will every move, so I only need to build the tree once. A BVH tree is a bounding volume hierarchy, where the scene is effectively divded into multiple areas of axis aligned bounding boxes (AABB). This means instead of only doing a ray - sphere intersection, I do a ray - box intersection using the slab method. This cuts down the search space and only iterate on the spheres that are within the AABB.
After implementing a BVH Tree and running this on the CPU ray tracer, the entire pipeline took about 12727ms or about 12.6s. That’s a massive performance increase! But, a 12 second renderer is still not that great in my opinion. Like this is a CPU ray tracer, this will never be used in a game for realtime rendering. The GPU does a much better job at that if you’re trying to aim for 16 ms frame times. But, I’m trying to see how well TaskGraph can perform.
Introducing SIMD
Now, the primary way where I can get a massive performance improvement is through utilizing SIMD, or single instruction multiple data.
I think one of the most common misconceptions with SIMD is just replacing the scalar types with instrinsics types. The reason why it’s a common misconception is because people often do not think of how much can get loaded into a wide register.
For example, if I try to load a series of Vector3s, that is 12 bytes loaded and each word is 4 bytes. In a
register that is 32 bytes wide, I can only load 2 Vector3s or 24 bytes. We have 8 bytes remaining that
only represents two 4 byte words.
Take a look at the example below, the last 2 lanes in the register cannot load another Vector3, effectively leaving only the x & y components to load.
|----------------Register---------------|
| x1 | y1 | z1 | x2 | y2 | z2 |----|----|
|---------------------------------------|
To make full use of a wide register, I opted to split Vector3s into Vector<float>s for each component in
a coordinate system like in the diagram below.
|----------------Register---------------|
| x1 | x2 | x3 | x4 | x5 | x6 | x7 | x8 |
|---------------------------------------|

|----------------Register---------------|
| y1 | y2 | y3 | y4 | y5 | y6 | y7 | y8 |
|---------------------------------------|

|----------------Register---------------|
| z1 | z2 | z3 | z4 | z5 | z6 | z7 | z8 |
|---------------------------------------|
This means I can load 8 coordinates into 3 different registers and process them simultaneously. However, this made the ray tracer a little more complex. For example, for each ray, I have to check if it collides with a sphere. If a ray collides, it has to calculate the color of the surface, otherwise it calculates the color of the sky.
The problem is the “if condition”. Each lane represents a coordinate and with SIMD, I effectively fire 8 rays simultaneously.
In typical scalar code the pseudocode would look something like this:
foreach (ray in rays) {
    if (ray.Hit(...)) {
        switch (hitObject.MaterialType) {
            case Lambert:
                color += CalculateLambertContribution(...);
            case Metallic:
                color += CalculateMetallicContribution(...);
            case Glass:
                color += CalculateGlassContribution(...);
        }
    } else {
        color += ComputeSkyContribution(...);
    }
}
In scalar code, we would iterate each lane and then check, but SIMD does not have a parallel “if” condition. The best strategy I can come up with effectively computing all of the listed work regardless of the actual material type or whether or not it hit anything:
- Shoot ray
- If it hits something, compute the color contribution regardless of material type
- It it does not hit anything, compute the color contribution from the sky
This means each ray calculates the contribution of lambert, metallic, and glass materials in the scene. With SIMD code, to handle the if conditions, I use a mask for each “lane”. For example, consider the lambert contribution below.
|------------Register-----------|
| 0 | 1 | 2 | 3 | 4 | 5 | 6 | 7 | Ray #
| 1 | 0 | 0 | 1 | 1 | 1 | 1 | 0 | Mask Result
|-------------------------------|
If my mask is 10011110 then it means that ray 0, 3, 4, 5, and 6 all contribute to the scene using the
lambertian lighting model. I still compute the lambert result for ray 1, 2, and 7, but I don’t use those
results. I do this for metallic and glass materials as well and I combine the results at the end.
It is a different way of thinking and it sounds like I am doing wasted work and yes, I am doing wasted work. But since I am processing 8 rays simultaneously per iteration that should make up for the amount of wasted work I am doing.
The Final Results
With my rays and lighting calculate all converted to SIMD, the same scene took about ~5500 ms to render and write to disk. That is ~5.5 seconds and is a massive improvement to the scalar code. I effectively cut the runtime in half!
Some closing thoughts
SIMD is important in writing efficient code, however with the current style, I adopted a predominantly
structure of arrays (SOA). This means, I had to write my own functions to compute common math functions found
within the Vector3 struct like dot product, length squared, etc.
I would like to adopt a array of structure of arrays (AOSOA) for the API convenience when utilizing SIMD. Additionally, this demo serves as good benchmark for profiling and optimizing TaskGraph.